Autonomous penetration testing on your own infrastructure. Pick a target and launch the attack.
Authorized. Under your control. In your network.
- 01Reconnaissance
- 02Foothold
- 03Escalation
- 04Lateral movement
- 05Proof of impact
- 06Report & remediation
Reactive defense can’t keep up.
The time from an exploit’s release to the first attack has shrunk from years to hours. The attack surface grows faster than a team can check it by hand — and traditional manual penetration testing depends on the availability and experience of the people who run it. Autonomous, agentic penetration testing (agentic AI) uses artificial intelligence to keep up: you run it as often as you need, and every time you get a real path to the objective — not a list of “maybes”.
Pentester quality. Agent scale.
A manual pentest usually delivers good quality, but only as often as the number of testers on the team allows. A scanner delivers scale, but with it noise and false positives. WORKBENCH removes both limits: quality and frequency at once.
- Manual pentest
High quality, but once a year and a narrow slice.
- Scanner
Large scale, but hundreds of alerts without proof.
- Our service
Pentester quality at agent scale, after every major release.
A scanner sees individual bugs.
An attacker chains them into a path to the objective.
WORKBENCH doesn’t stop at a list of vulnerabilities. It chains them into a scenario, exploits them one by one and shows where they really lead — from the first foothold to critical business impact.
Reconnaissance
Maps subdomains, hosts, services and endpoints. The full picture before the first shot is fired.
Foothold
Exploits the first real vulnerability — evidence from action, not a version from a header.
Escalation
Elevates privileges and chains individual bugs into one working chain.
Lateral movement
Moves on to further systems, accounts and data — like a real attacker.
Proof of impact
Shows where the path really leads and what sits at the end of it.
Report & remediation
Every finding with evidence, a CVSS score and a concrete recommendation for the team.
Five steps. One run.
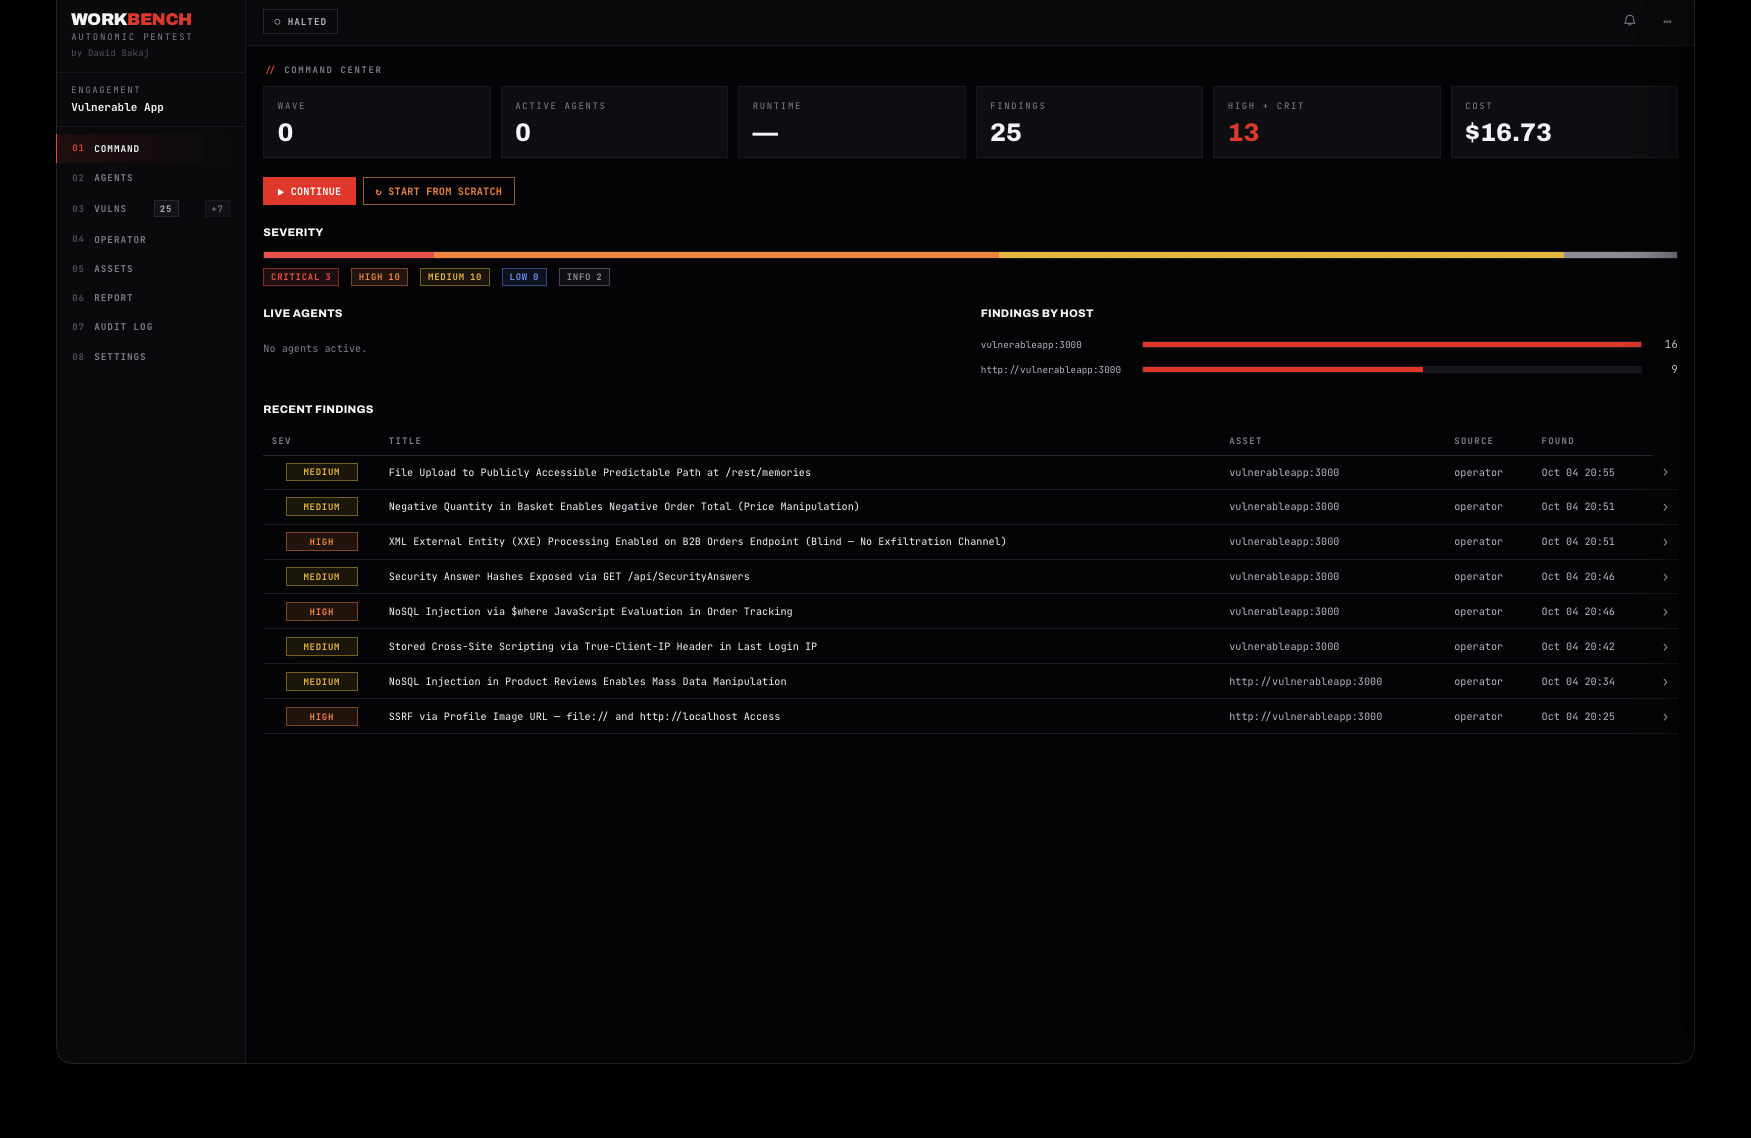
A single run goes from setting the boundaries all the way to a finished report. Below are screenshots from the live platform — the target is a deliberately vulnerable application in an authorized lab.
You start with boundaries
You set targets, exclusions and the exploitation level before the start. Denial-of-service attacks are disabled by default.
- Targets and exclusions
- Exploitation level
- Privilege profile
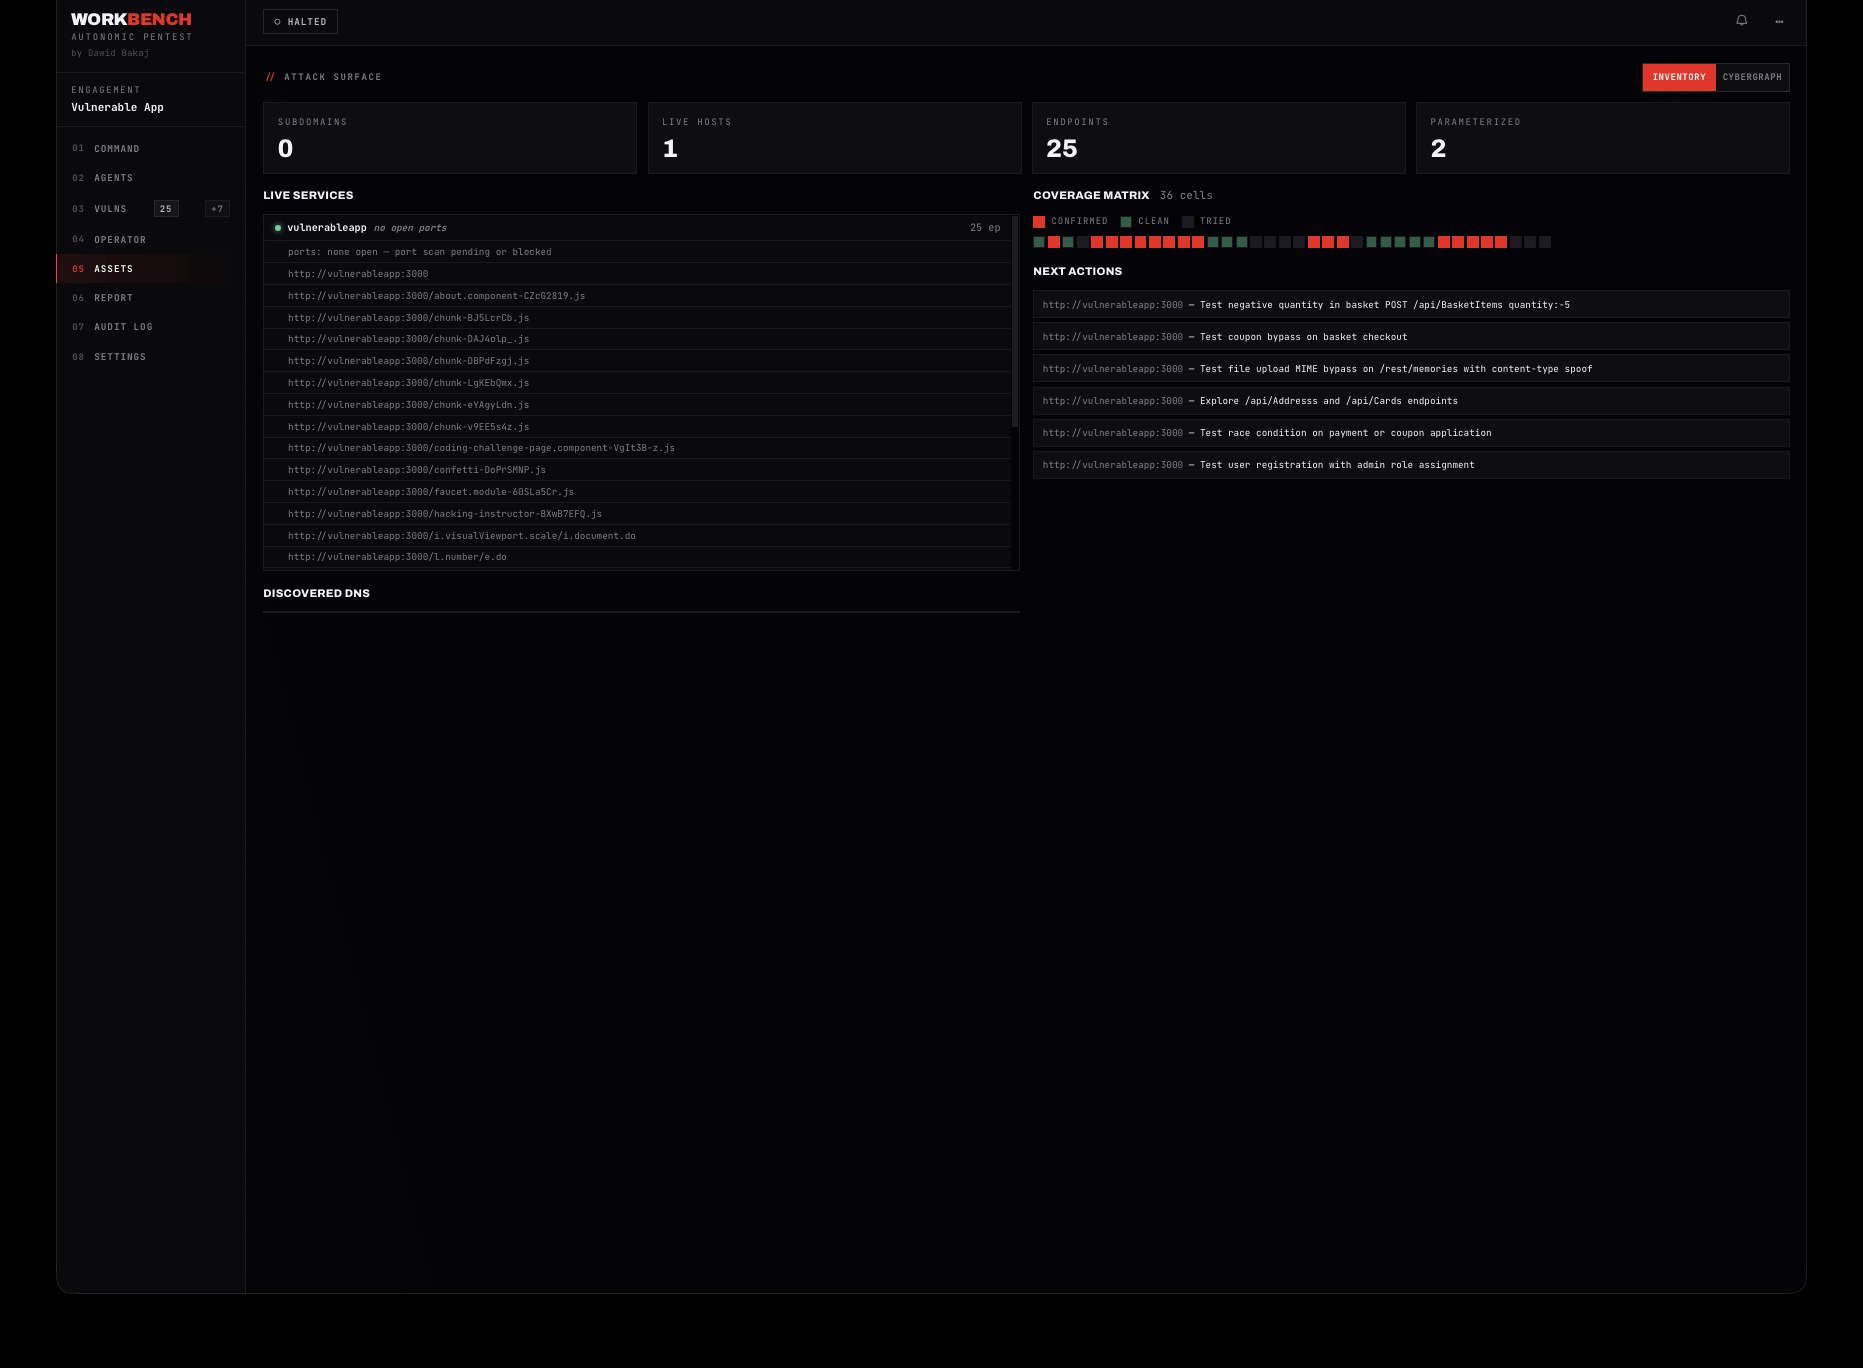
Maps the attack surface
The swarm collects subdomains, hosts, services and endpoints, and the coverage matrix shows what has already been checked.
- Asset inventory
- Coverage matrix
- Action queue
Proves, doesn’t guess
Every finding with a proof-of-concept, a CVSS score and a recommendation. A separate step screens out false positives.
- A PoC for each one
- CVSS and vector
- “Verified” status
Shows the real path
Hosts, services, credentials and findings in one graph — exposure as paths, not table rows.
- Attack graph
- Risk rings
- One view of the estate
Delivers a finished result
Executive summary, scope, methodology and findings with evidence — exported to a report ready for the client and the auditor.
- Summary and scope
- Findings with CVSS
- Report export
One engine. Many kinds of tests.
WORKBENCH runs tests autonomously, while you choose the scope and depth. From a single application to an entire infrastructure and cloud.
Application security
The full cycle: from a map of features to exploiting vulnerabilities in business logic.
Application securityPenetration testing →Web applications and API
OWASP Top 10, access control, injection, IDOR and API vulnerabilities — including authenticated (greybox) testing with multiple roles.
Web · API · greyboxWeb application testing →Network infrastructure
External and internal testing: from internet-facing exposure to lateral movement inside the local network.
Internal + externalInfrastructure testing →Red team operations
Scenarios close to a real attack, carried out within agreed rules.
Red team opsRed Team →Cloud testing
Configuration, identities and permissions in AWS, Azure and GCP — escalation paths in the cloud.
Cloud pentestCloud penetration testing →Reconnaissance and OSINT
Mapping subdomains, assets and leaks — the full picture of the attack surface before someone else does it.
Recon & OSINTOSINT & reconnaissance →- 6steps from scope to report
- 100%critical success rate
- 99%false positive check
- ∞unlimited agent dispatch
An isolated execution runtime.
Today the platform runs on our infrastructure (when our operator runs the test) or entirely on yours (on-prem). A SaaS version — with a fully isolated tenant and its own toolbox for every client — is in preparation. In every variant, tools run inside an isolated container (pentest-toolbox) and the backend only orchestrates them.
SHARED FILE SYSTEM — one store that every agent reads from and writes to. Findings, dumps and artifacts in one place.
“Full autonomy and decision-making. The agent sets its own priorities based on signals from the engagement — what it has already found, what looks promising and where the path leads. When the first attempt fails, it adapts the plan and directs power to where it really leads to the objective. You set the boundaries — it picks the next move.
— the principle WORKBENCH is built on
no data flow between tenants
no data flow between projects
Cybergraph.
Every host, service and finding from a run is stored and typed. The next run starts from what you already know — instead of scanning everything from scratch.
Traversal
Relationships map to MITRE ATT&CK techniques, and a finding points to a specific vulnerability. The graph links the whole estate into one searchable whole.
Human in the loop. You decide.
Autonomy doesn’t mean “unsupervised”. In interactive mode the swarm asks about key decisions, and you can steer the run at any moment — with an ordinary conversation.
The agent asks before it acts
At key forks the swarm pauses and waits for your approval. You pick one of the suggestions or type your own command — nothing important happens without you.
- Pauses at the intrusiveness threshold
- Ready-made options or your own answer
- Full decision context on screen
Steer the run with a conversation
The operator-agent chat works like a conversation with the person running the test. Ask about status and priorities, set the next actions, add or change the scope and authentication profiles — mid-run.
- Status and priorities on demand
- Change scope and auth profiles
- Set the next actions on the fly
Autonomy that never slips out of control.
Offensive power only makes sense with hard guardrails. You set the scope, permissions and boundaries before the start — the platform enforces them throughout the run.
Human in the loop and over the loop
You see every step live. At any moment you take control without killing the run.
Group kill switches
Stop one operation or every operation in a given area with a single switch.
ROE boundaries
You set forbidden actions, the exploitation level and the privilege profile before the start. DoS disabled by default.
Sandbox on your host
Tools run in the pentest-toolbox container on a machine you designate — not on our backend.
Out-of-band testing
Optional validation over OOB channels (interactsh) confirms “blind” vulnerabilities.
ProxyGuard
The option to route agent traffic through a Burp or Caido proxy — full visibility and interception.
Persistent audit log
Every command, approval and artifact with a timestamp. You can replay the run step by step.
Your backend and database
You can keep the backend and data on your side — in a private cloud or on-premise.
Engagement models.
We prepare the quote for your scope and engagement model.
Operator on our side
Our expert, certified to at least OSCP, runs the test on our infrastructure in the EU. You get the findings, the report and a retest.
- Pay per project: you pay for a specific test of an application, API or perimeter
- Subscription: a fixed fee, tests after every major release
- Retest after fixes
- No deployment: no hardware, licences or AI tokens on your side
On-premise
Workbench installed in your infrastructure, with the AI model of your choice, including a local one.
- Data never leaves your network
- Tests are run by our operator in your installation or by your team after training
- Requires your server, an AI model and your team’s share in maintenance
SaaS
Workbench in our cloud, with an isolated environment for every client. In preparation — not available for purchase yet.
- Isolated tenant with its own toolbox and data
- Your AI model and API cost on your side
- No installation and no server to maintain
Want to be among the first clients? Get in touch.
Integrations from the real battlefield.

SysReptor
Reporting

SysLeaks
Threat intelligence

Interactsh
Out-of-band testing
NVD · KEV · EPSS
Vulnerability management


Burp · Caido
Proxy & HTTP traffic analysis
API · MCP
Automation & orchestration
Bedrock · Azure
AI models
Built-in tools · pentest-toolbox
Over 40 professional tools shipped inside an isolated container — all ready to run from the start, no setup. The agent reaches for them on its own, and the list keeps growing.
 Nmap
- masscan
 Amass
- subfinder
- dnsx
- naabu
- httpx
- katana
- Nuclei
- interactsh
 ffuf
- Gobuster
- Nikto
 SQLMap
- ghauri
- Arjun
- gau
 jsluice
 WPScan
 Semgrep
 Trivy
- Shodan
 NetExec
 BloodHound
 Impacket
- Kerbrute
- Certipy
- Evil-WinRM
- enum4linux-ng
- rpcclient
- smbclient
- ldapsearch
- Responder
 Hashcat
- Hydra
- theHarvester
- Recon-ng
- ExifTool
- FOCA
 Sherlock
- Maigret
- Holehe
- Blackbird
- GHunt
- h8mail
- PhoneInfoga
- Osintgram
You tune the engine for the task: backend, mastermind model, specialist model, working mode, the number of parallel agents and the wave and time limits. The platform configures itself to keep costs in check.
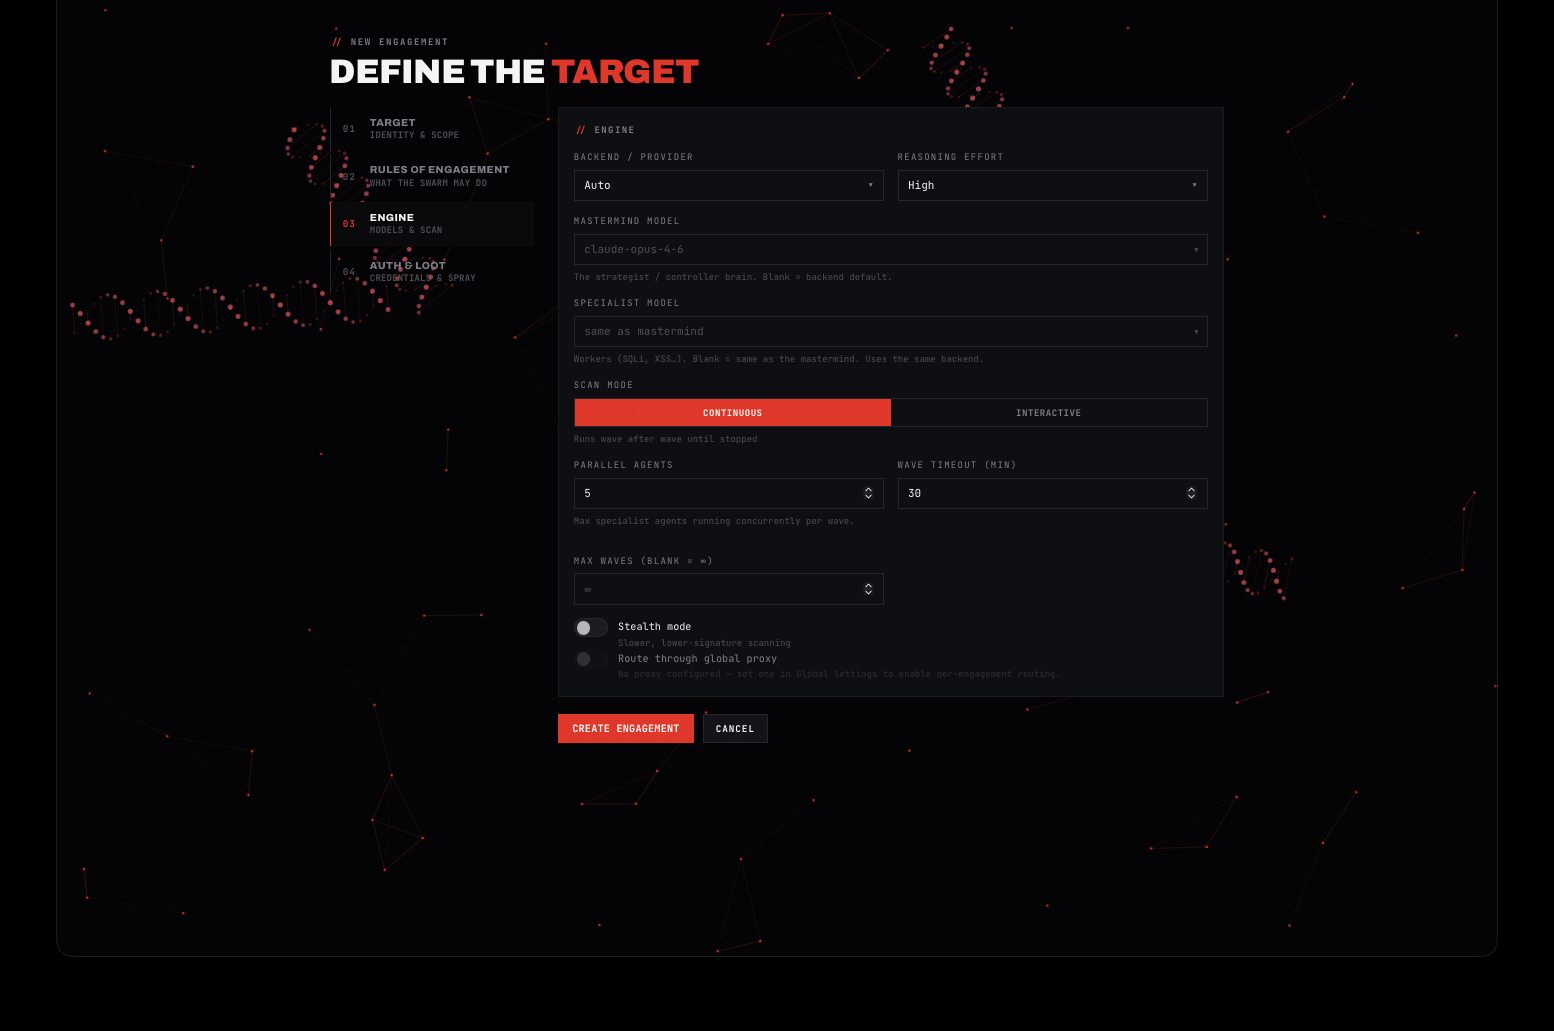
Any model, cloud or local.
You connect your own account and pay for tokens directly to the provider. You separately choose the model for the “mastermind” and for the specialists, as well as the reasoning effort level. We provide the platform, the agent swarm, reporting and updates.
- Claude
- GPT
- Gemini
- DeepSeek
- Kimi
- GLM
- Qwen
via AWS Bedrock, Azure AI, API, OpenRouter or an OpenAI-compatible gateway
- Qwen
- Llama
- gpt-oss
- Gemma
- DeepSeek
via Ollama, llama.cpp or vLLM, on your hardware
how far the best open-weight model trails the frontierEpoch AI, Cyber ECI, October 2026
Cyber ECI · cybersecurity capabilities
closedopen-weight- Claude Opus 5.5Anthropic · closed171.14
- GPT-6 AstraOpenAI · closed171.03
- GLM-5.3Z.ai · open-weight≈ 6–7 mo.160.10
- Kimi K3Moonshot · open-weight157.60
- GLM-5.2Z.ai · open-weight154.12
- Gemini 3.1 ProGoogle DeepMind · closed153.55
- DeepSeek-V4-ProDeepSeek · open-weight150.35
No training on data from your tests
We call cloud models through enterprise platforms. Prompts, findings and reports are not used to train models and are not shared with the provider’s other customers.
- Prompts and results do not train models
- Nothing shared with the provider’s other customers
- A model per role: stronger for the strategist, faster for the specialists
- The administrator decides which models may be used
Amazon does not store prompts or completions and does not use them to train models.
Microsoft does not use prompts or completions to train foundation models.
The model runs on your server — even in an environment cut off from the internet.
Who WORKBENCH is for.
Security teams and CISOs
Run autonomous penetration testing on systems you designate yourself, in your own environment. Check your exposure more often than your team’s calendar allows.
Request a demoPentesters and red teams
Hand reconnaissance and repetitive exploitation attempts to the swarm, and focus on attack chains and interpretation. More engagements with the same team.
Try itSoftware houses and IT providers
Build repeatable security testing into your release cycle and show clients proof that the application was tested offensively — on your infrastructure.
Let’s talkFrequently asked questions
Didn’t find your answer? Write to us — we respond within one business day.
Ask your own questionCan this tool disrupt production systems?
Yes, we cannot rule it out. WORKBENCH was built for maximum effectiveness and efficiency, so there is no way to guarantee that the actions taken by the agents will not disrupt a system. That is why on production systems we recommend working in interactive mode (human-in-the-loop) — the agent pauses and waits for your approval before critical steps — rather than continuous mode. In addition, the default profile is non-destructive (proof-only), and denial-of-service attacks remain disabled.
How is autonomous penetration testing different from a vulnerability scanner?
A scanner matches software versions against a database of known bugs and returns a list of “possible” issues, some of which do not exist. WORKBENCH runs an autonomous test: a swarm of AI agents maps the attack surface, forms hypotheses, tries to actually exploit vulnerabilities and chains bugs into scenarios. Every finding gets a proof-of-concept, a CVSS score and a recommendation. That is the difference between a list of warnings and a confirmed path to the objective.
Does it replace a human pentester?
No. The platform accelerates and scales your team’s work: it takes over reconnaissance, repetitive exploitation attempts and report assembly, while the operator controls the scope, approves actions and interprets the result. A human sees every step and can take control or stop the run at any moment.
Which AI model does the platform use and who pays for the API?
With an on-premise licence you choose the model and connect your own provider: Claude (Anthropic), OpenAI, OpenRouter or a local model (Ollama, llama.cpp, vLLM). You settle token costs directly with your provider. We deliver the platform and updates; you pay for the API only for what you actually use. When our operator runs the test on our infrastructure, the model and tokens are on our side.
Can I run the platform in my own infrastructure or offline?
Yes. The execution tools run in a container (pentest-toolbox) on a host that you designate yourself — not on our backend. You can deploy the on-premise licence on your own servers or in a private cloud, and with a local model even in an environment cut off from the internet.
How does the platform enforce the test boundaries (ROE)?
Before the start you define the Rules of Engagement: targets and exclusions, forbidden actions (denial-of-service disabled by default), exploitation level and privilege profile. Above the agreed level the agent pauses and waits for your approval. You also get group kill switches and a persistent audit log with every command.
Do findings include evidence and are they verified?
Yes. Every finding includes a proof-of-concept, the affected components, the outcome and a remediation recommendation, and a separate step screens out false positives. Unconfirmed vulnerabilities are flagged, and confirmed ones get a “verified” status.
Is it safe for production environments?
The platform is intended solely for testing targets that you authorize yourself, and it operates within ROE boundaries. The default profile is non-destructive (proof-only), DoS is disabled, and secrets touched by the agent are masked before they reach a log or report.
What does licensing and pricing look like?
There are two models: a service where our operator runs the test (pay per project or a subscription with retest), and an on-premise licence on your infrastructure — then you cover the API cost of your own model separately with your chosen provider. A SaaS model is planned. We prepare the quote for your scope and engagement model. Write to us for a quote and demo access.
Time is running out. For attackers too.
Book a demo slot. We’ll run WORKBENCH against a sample, authorized target and you’ll see live what the platform finds, how it chains vulnerabilities into an attack path and how long a run takes from scope to report.
- Slot bookingWe reply within 24 h on business days, propose a time and agree on the demo target.
- Live demo under NDAWe run the platform against an authorized target. You see every agent step and every operator decision.
- You check effectiveness and efficiencyYou assess the results of the run: findings with evidence, confirmed attack paths and the time from scope to report. No obligation.
- Demo on an authorized target
Book a WORKBENCH demo slot
Briefly describe what you want to check and which target we can use for the demo. We will propose a time within one business day.